Related Topics:
Troubleshoot Visual Studio Code-
Number of AI optical modules
Total shipments of leading-edge datacom optical modules are projected to tally over US$9 billion for 2024, according to the latest Optical Components Report from research firm Cignal AI. While the industry-standard OSFP (Octal Small Form-Factor Pluggable) module has successfully enabled 400Gbps, 800Gbps, and 1. 8Tbps of switching. Unlike traditional enterprise or cloud data centers, AI factories are purpose-built to support large-scale AI training and inference workloads, such as large language models (LLMs), multimodal foundation models, and real-time generative AI services. Unit shipments of 400G and 800G modules have grown nearly fourfold over the past 12 months and are expected to. With 1. Yole Group attended OFC 2026 with a dedicated team of analysts on site, actively engaging with major players in the photonics. This report explores the evolving role of optics in AI Clusters, covering both connectivity and switching. Importantly, the forecast includes.
[PDF Version]
-
First AI Server in Northern Europe
We're launching Stargate Norway—OpenAI's first AI data center initiative in Europe under our OpenAI for Countries program. (“Nscale”), Aker ASA (“Aker”) and OpenAI today announced the launch of. In a landmark move for European AI infrastructure, Nscale Global Holdings, Aker ASA, and OpenAI have unveiled Stargate Norway: a major new gigafactory project in Narvik, Northern Norway. The companies plan is to invest 10 billion Norwegian kroner in the first phase of the project, called “Stargate Norway. The site aims to deliver 100,000 NVIDIA graphics processing units (GPU) by the end of 2026.
[PDF Version]
-
Focusing on AI Computing Servers
AI model training and inference workloads are forcing the industry to rethink not only how much compute fits in a rack, but how servers are architected from end to end — transforming computing infrastructure as we know it. Explore the IP that enables high-performance . Modern AI models are data-hungry, computation-heavy beasts that need specialized hardware just to function, let alone perform at their best. That's the job of an AI server—a custom-built system that keeps AI applications fast, scalable, and efficient. An AI server's architecture is all about. Artificial Intelligence (AI) server manufacturers have experienced surging demand as data center operators require significantly more computing power than before the advent of ChatGPT and other Generative Artificial Intelligence (Gen AI) tools. They provide the hardware environment —. AI has been studied for decades, and generative AI has been used in chatbots as early as the 1960s. However, the release on November 30, 2022, of the ChatGPT chatbot and virtual assistant took the IT world by storm, making GenAI a household term and starting off a stampede to develop AI-related.
[PDF Version]
-
AI decoding server
This document shows how to use Speculative Decoding with vLLM to reduce inter-token latency under medium-to-low QPS (query per second), memory-bound workloads. The pace of generative AI (gen AI) innovation demands powerful, flexible and efficient solutions for deploying large language models (LLMs). Today, we're introducing Red Hat AI Inference Server. To train your own draft models for optimized speculative decoding, see vllm-project/speculators for seamless training and integration with. This tutorial shows how to build and serve speculative decoding models in Triton Inference Server with vLLM Backend on a single node with one GPU. This reduces the number of infer requests to the main model, increasing performance. Type $help for helpful information! The second best way is to use cargo install ciphey and call it with ciphey. You can also git clone this repo and run docker build. Weave CLI unifies 11 vector databases into one workflow.
[PDF Version]
-
What to do if the AI diagnostic server malfunctions
· Make sure firewalls or other security solutions are not blocking the connection to the AI server – if this looks to be the case, get in touch with the customer's IT to create an exception. · Reboot the PC – sometimes the solution is as simple as that. Is the AI integration even being installed? Please go to Windows Settings -> Apps and search the list for “coDiagnostiX”. In this comprehensive report, we analyze the cybersecurity requirements for AI-enabled medical devices from multiple perspectives: regulatory frameworks, technical standards, threat landscape, and real-world case studies. You need a Pro Plus or Enterprise Plus SKU to use AI Agents. This guide outlines common error messages and actionable steps to troubleshoot them.
[PDF Version]
-
How to add AI to the server interface
By setting up your local AI server today, you're preparing for an AI future where control, privacy, and customization are in your hands. Instead of depending on cloud APIs, you can bring the intelligence directly onto your own hardware, which unlocks: Improved privacy and security: With locally hosted AI, your data never. In my case, I set up a new, separate system with one purpose, as an AI server. The. To begin with, this comprehensive guide dives into a concept inspired by the principles of the Model Context Protocol (MCP). Nevertheless, we showcase a custom AI server built using JavaScript, deployed on AKS, and seamlessly integrated with Azure OpenAI. Running LLM locally offers several advantages, especially for users concerned with. In this guide, you will learn how to run advanced models such as Llama 3, Mistral, Phi-3, and Gemma locally on Windows and connect them with SQL Server through MCP to get smart, natural-language insights while keeping all your data completely private. Let me be direct about something: I'm not neutral on this topic.
[PDF Version]
-
10G AI server for local area network
Build your own private AI infrastructure with the right hardware. Compare workstations, NAS storage, and 10GbE networking for running LLMs locally—from $2,500 starter labs to $15K enterprise setups. If you make a purchase through these. Running AI models on a local AI server is one of the most empowering steps you can take in your AI journey. After spending three months testing every major local AI platform, benchmarking 15+ hardware configurations, and documenting setup processes that actually work, I've built a system that runs GPT-4 class models. A comprehensive guide to building fully open-source, local, and capable AI systems with complete privacy, customization, and offline capabilities. 230+ guides, tools, and community links.
[PDF Version]
-
AI Server Gap
Air-gap backups are a data storage tactic for disaster recovery where organizations copy critical data to a system or network that isn't easily accessible over the internet. After a threat passes, like a ransomware attack, the organization can access these protected backups to restore. Credit: VentureBeat made with Midjourney Cirrascale Cloud Services today announced it has expanded its partnership with Google Cloud to deliver the Gemini model on-premises through Google Distributed Cloud, making it the first neocloud provider to offer Google's most advanced AI model as a fully. Many AI tools have a seemingly benign "phone home" function — calling a remote server for updates, checking for new features, etc. For most software teams, integrating AI tools like code assistants is as simple as signing up for a service and adding an extension. You get. Deploy AI in air-gapped environments with zero internet dependency. Compare 7 enterprise platforms, learn deployment steps, and evaluate compliance for defense, finance, and healthcare. Air is a fundamentally poor thermal conductor. The concept is simple: if a.
[PDF Version]
-
How to identify the beam splitter code
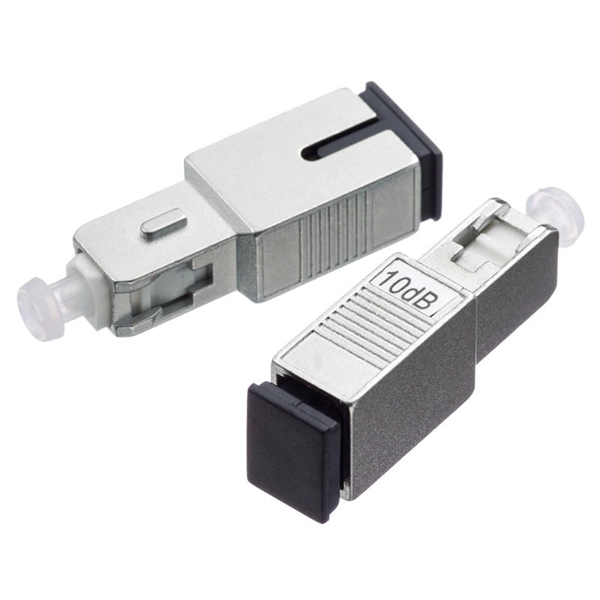
This package uses the AbstractTrees. jl interface in order to represent the splitting of BeamletOptics. Beamsplitters are used to split beams of light, enabling the separation of an incoming beam into reflected and transmitted parts. AbstractBeamsplitter interface. This type loosely defines the interaction logic used for the tracing. Use this beam splitters buying guide to compare major types, define selection criteria, and find suppliers: 🔬 Encyclopedia article: beam splitters 📦 Top-level product category: optical components and devices Click on a logo to get to the details of that supplier's offer. One of the biggest challenges for modeling such a system is that multiple ray paths cannot be simultaneously traced in Sequential Mode. It is a crucial part of many optical experimental and measurement systems, such as interferometers, also finding widespread application in fibre optic telecommunications.
[PDF Version]
-
Is wavelength division multiplexing WDM the same as code division multiplexing CDM
The Wavelength Division Multiplexing (WDM) system encompasses two distinct wavelength patterns: Coarse Wave Division Multiplexing (CWDM) and Dense Wavelength Division Multiplexing (DWDM). Multiplexing is a technique used in telecommunications and computer networks to combine multiple signals or data streams into a single transmission medium. The subsequent discussion will delve into a comprehensive introduction of. Frequency division multiplexing is defined as a type of multiplexing where the bandwidth of a single physical medium is divided into a number of smaller, independent frequency channels. These technologies will be further explored in detail.
[PDF Version]
-
New Territory AI Server
I hope you will join us on Isla Newbiefriendly server. Welcome everyone!Fixed Rewrote AI spawning system. Still needs a lot of improvements and balancing but at least AI won't respawn too soon like was happening before. Issues with collecting items from cooking contents slots Bear walk animations Small. A new version of FX is available! Click the "Update" button below to update The latest version of FX Client doesn't support custom lobbies yet. Use the stable version at https://fxclient. Geopolitical risks and rising competition threaten Nvidia's dominance in China's AI hardware market. Engage in discussions and collaborate with a vibrant group of gamers. Join on Discord! Youtube Discover an extensive STFC Officer Tool by StewieDøø.
[PDF Version]
-
Sri Lanka AI Server Costs
This comprehensive guide exposes the true economics of AI-ready data centers, providing actionable AI server data center cost and proven optimization strategies that can save your organization hundreds of thousands of dollars. What you'll learn:Artificial Intelligence has moved from experimentation to real-world execution across industries such as healthcare, fintech, eCommerce, logistics, and manufacturing. Businesses are no longer asking whether they should adopt AI. They are asking how fast they can implement it and how. If you're planning an AI deployment and your calculations focus primarily on hardware acquisition costs, you're heading toward a financial shock. → Sri Lanka has 10+ established AI companies serving industries from tourism. Power your business with Hybrid AI Lenovo's broad portfolio of ThinkEdge and ThinkSystem servers enable you to accelerate and scale AI solutions efficiently while managing and protecting all your data. Our transparent pricing ensures you get the best value for your investment in digital presence.
[PDF Version]