Related Topics:
Enyo Advanced Gangs Crews-
Focusing on AI Computing Servers
AI model training and inference workloads are forcing the industry to rethink not only how much compute fits in a rack, but how servers are architected from end to end — transforming computing infrastructure as we know it. Explore the IP that enables high-performance . Modern AI models are data-hungry, computation-heavy beasts that need specialized hardware just to function, let alone perform at their best. That's the job of an AI server—a custom-built system that keeps AI applications fast, scalable, and efficient. An AI server's architecture is all about. Artificial Intelligence (AI) server manufacturers have experienced surging demand as data center operators require significantly more computing power than before the advent of ChatGPT and other Generative Artificial Intelligence (Gen AI) tools. They provide the hardware environment —. AI has been studied for decades, and generative AI has been used in chatbots as early as the 1960s. However, the release on November 30, 2022, of the ChatGPT chatbot and virtual assistant took the IT world by storm, making GenAI a household term and starting off a stampede to develop AI-related.
[PDF Version]
-
First AI Server in Northern Europe
We're launching Stargate Norway—OpenAI's first AI data center initiative in Europe under our OpenAI for Countries program. (“Nscale”), Aker ASA (“Aker”) and OpenAI today announced the launch of. In a landmark move for European AI infrastructure, Nscale Global Holdings, Aker ASA, and OpenAI have unveiled Stargate Norway: a major new gigafactory project in Narvik, Northern Norway. The companies plan is to invest 10 billion Norwegian kroner in the first phase of the project, called “Stargate Norway. The site aims to deliver 100,000 NVIDIA graphics processing units (GPU) by the end of 2026.
[PDF Version]
-
AI decoding server
This document shows how to use Speculative Decoding with vLLM to reduce inter-token latency under medium-to-low QPS (query per second), memory-bound workloads. The pace of generative AI (gen AI) innovation demands powerful, flexible and efficient solutions for deploying large language models (LLMs). Today, we're introducing Red Hat AI Inference Server. To train your own draft models for optimized speculative decoding, see vllm-project/speculators for seamless training and integration with. This tutorial shows how to build and serve speculative decoding models in Triton Inference Server with vLLM Backend on a single node with one GPU. This reduces the number of infer requests to the main model, increasing performance. Type $help for helpful information! The second best way is to use cargo install ciphey and call it with ciphey. You can also git clone this repo and run docker build. Weave CLI unifies 11 vector databases into one workflow.
[PDF Version]
-
How to add AI to the server interface
By setting up your local AI server today, you're preparing for an AI future where control, privacy, and customization are in your hands. Instead of depending on cloud APIs, you can bring the intelligence directly onto your own hardware, which unlocks: Improved privacy and security: With locally hosted AI, your data never. In my case, I set up a new, separate system with one purpose, as an AI server. The. To begin with, this comprehensive guide dives into a concept inspired by the principles of the Model Context Protocol (MCP). Nevertheless, we showcase a custom AI server built using JavaScript, deployed on AKS, and seamlessly integrated with Azure OpenAI. Running LLM locally offers several advantages, especially for users concerned with. In this guide, you will learn how to run advanced models such as Llama 3, Mistral, Phi-3, and Gemma locally on Windows and connect them with SQL Server through MCP to get smart, natural-language insights while keeping all your data completely private. Let me be direct about something: I'm not neutral on this topic.
[PDF Version]
-
Liquid-cooled charging piles AI server power supplies Huawei data center
This article discusses the necessity and benefits of liquid cooling in AI data centers, focusing on the challenges posed by high-power AI servers and the advantages of Vertical Power Module (VPM) systems. AI applications, high-performance computing, and GPU servers have driven the power consumption of a data center rack as high as 20 kW, 30 kW, or even 50 kW. To address this challenge, Huawei. AI factories are pushing data center power and cooling requirements beyond traditional limits, making integrated AI data center infrastructure essential. Why space limitations, power-delivery constraints, cooling inefficiencies, and sustainability pressures present challenges for scaling legacy data centers. How. NJFX and Bala Consulting Engineers are collaborating to develop a data hall, internally named Project Cool Water, which represents the first purpose-built cable landing station campus in North America to support “liquid-to-the-chip” AI-ready infrastructure. Over the past three years, we've tracked.
[PDF Version]
-
10G AI server for local area network
Build your own private AI infrastructure with the right hardware. Compare workstations, NAS storage, and 10GbE networking for running LLMs locally—from $2,500 starter labs to $15K enterprise setups. If you make a purchase through these. Running AI models on a local AI server is one of the most empowering steps you can take in your AI journey. After spending three months testing every major local AI platform, benchmarking 15+ hardware configurations, and documenting setup processes that actually work, I've built a system that runs GPT-4 class models. A comprehensive guide to building fully open-source, local, and capable AI systems with complete privacy, customization, and offline capabilities. 230+ guides, tools, and community links.
[PDF Version]
-
How to set up an AI Xiaozhi server
This document provides instructions for deploying the xiaozhi-server platform. For setting up a local development. If the network configuration page does not automatically redirect, you need to manually open the browser and visit 4G is supported, the maximum compatibility option should be turned on for iPhone hotspot). The SSID. XiaoZhi AI is an open-source intelligent voice robot based on ESP32-S3 development, integrating wake word detection, AI conversation, device control, and multi-protocol communication capabilities. Through this project, we aim to help more people get started with AI hardware development and understand how to integrate rapidly evolving large language models into actual. This project applies the Media Kit to implement an AI voice assistant, which requires a certain level of programming proficiency as well as familiarity with ESP-IDF and open-source large models.
[PDF Version]
-
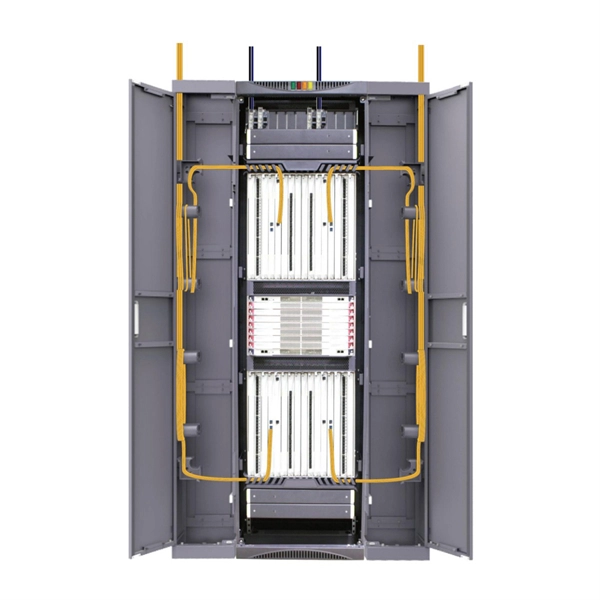
Why do AI computing power require optical modules
Using advanced optical modules boosts AI system speed and bandwidth, helping handle large data loads with low delay and high efficiency. Understanding their role is key to building efficient, scalable AI systems. Optical modules convert electrical signals into light to move data quickly and reliably in. Optical modules perform the task of converting optical and electrical signals in network connections, responsible for converting electrical signals into optical signals at the transmitting end, and then converting optical signals into electrical signals at the receiving end after transmission. Feeding AI models with high-dimensional data at hyperscale demands infrastructure that can move terabits per second with minimal loss and minimal power draw. Community-driven hyperscale innovation for all.
[PDF Version]
-
AI Server Liquid Cooling Structure Design
This in-depth guide covers everything from cold plate manufacturing and assembly to development requirements and rigorous testing methods, helping engineers and data center operators optimize AI server liquid cooling systems for reliability and performance. Many AI servers with accelerators (e., GPUs) used for training LLMs (large language models) and inference workloads, generate enough heat to necessitate liquid cooling. These servers are Discover additional documents & tools reserved for our partners. → Send your drawings to get engineering feedback. Microsoft is continuously architecting and optimizing every layer of the cloud and AI infrastructure stack to meet the demands of our AI advancements. Modern AI systems powering AI workloads demand higher power at higher densities, leading to a need to develop new methods of cooling to manage heat.
[PDF Version]
-
What to do if the AI diagnostic server malfunctions
· Make sure firewalls or other security solutions are not blocking the connection to the AI server – if this looks to be the case, get in touch with the customer's IT to create an exception. · Reboot the PC – sometimes the solution is as simple as that. Is the AI integration even being installed? Please go to Windows Settings -> Apps and search the list for “coDiagnostiX”. In this comprehensive report, we analyze the cybersecurity requirements for AI-enabled medical devices from multiple perspectives: regulatory frameworks, technical standards, threat landscape, and real-world case studies. You need a Pro Plus or Enterprise Plus SKU to use AI Agents. This guide outlines common error messages and actionable steps to troubleshoot them.
[PDF Version]
-
Estonian AI Server 100G
Get high-performance, scalable, and secure dedicated GPU hosting in Tallinn, Estonia — ideal for AI, machine learning, gaming, and deep learning projects. Onward connections to Saint Petersburg in Russia via 100G and Belarus via 10G links. The network boasts 35ms latency from end to end, capacity of 100G per channel and 9. Security: Your assets. Power your business with Hybrid AI Lenovo's broad portfolio of ThinkEdge and ThinkSystem servers enable you to accelerate and scale AI solutions efficiently while managing and protecting all your data. Why Choose Lenovo Hybrid AI solutions? Drive Real Outcomes with AI Services Everything you need. In July 2019, an expert group led by Ministry of Economic Affairs and Communications and the Government Office presented a policy report together with proposals to advance the up-take of AI in Estonia (Estonia, 2019a). Explore the pioneering compute technologies can accelerate your AI and HPC applications. Choose the dedicated server which is right for your business.
[PDF Version]
-
Are AI servers equipped with high-performance hardware
They use accelerators like GPUs and TPUs paired with high-bandwidth memory and fast NVMe storage for superior performance. Businesses that run real-time AI, custom model training, or privacy-sensitive workloads gain major speed and control advantages from dedicated AI infrastructure. AI servers are high-performance computing systems designed to process complex artificial intelligence workloads, including large-scale model training and real-time inference. We will also touch on cooling and power consumption. These systems support compute-intensive applications including large language models (LLMs), generative AI, computer vision, natural language processing, and advanced analytics at enterprise. AI servers are engineered with several distinctive features that set them apart from traditional servers: High-Performance GPUs: Equipped with powerful Graphics Processing Units (GPUs), AI servers excel at parallel processing, crucial for tasks such as deep learning and neural network training.
[PDF Version]
-
Recommended AI Server Manufacturers in Central Asia
ABI Research's AI Server OEMs competitive ranking assesses eight vendor portfolios. Download this report today to determine the Go-to-Market (GTM) strategies, innovations, and strengths and weaknesses of the top market players. Get the full ranking today!Beyond providing the physical hardware, customers have come to expect AI server Original Equipment Manufacturers (OEMs) to offer cooling technology, infrastructure management software, and professional services. Some server manufacturers outperform others in these areas. With a focus on reliability and scalability. The global AI server market is expected to be valued at USD 142. 83 million by 2030 and grow at a CAGR of 34. (US), Hewlett Packard Enterprise Development LP (US), Lenovo (Hong Kong), Huawei Technologies Co. This guide identifies top suppliers from China specializing in high-performance rack-mounted GPU servers with support for NVIDIA RTX 4090/5090, AMD EPYC, and Intel Xeon processors. —March 16, 2025— Aivres, a data center servers and storage solutions provider, announced that, at GTC 2026, the company will showcase its AI Factory.
[PDF Version]
-
Impact of AI on the Server Industry
This study evaluates the environmental footprint of AI server operations and examines feasible technological and infrastructural strategies to mitigate these impacts. A comprehensive report by Global Market Insights Inc. The market is expected to grow from USD 167. 56 trillion in 2034, at a CAGR of 28. 9% in 2024, continuously being squeezed out by budgets for AI servers. 5% YoY growth in 2024, to meet the strong demand of CSPs and OEMs generative AI training and inference. Those companies are signaling that the traditional server-centric model can't keep up with modern AI workloads that require raw processing power and high-bandwidth, low-latency communication between compute units. We're entering the era of “compute pods” – representing a brand new unit of compute. Artificial Intelligence (AI) is transforming industries from healthcare to finance, but its growth comes with a hidden cost: the enormous demand. Artificial Intelligence (AI) has revolutionized the way we approach business, but it has also had a significant impact on server consumption and infrastructure demands.
[PDF Version]
-
Domestic AI Inference Servers
A complete tutorial for building a production-ready AI inference server on dedicated GPU hardware. Covers framework selection, deployment, API design, monitoring, security, and scaling. It handles all the inference for you, so you just pick a model and go. But before you run anything, you need to figure out which model is right for you. The short answer is that it comes down to how much memory your machine has. Network Engineer and tech enthusiast. A local LLM inference server is a GPU-accelerated computing system that runs a large language model entirely on hardware your business owns or controls — with no data sent to cloud AI providers like OpenAI or Anthropic. A starter setup for a 7B parameter model costs $3,500–$6,000 in hardware; a. AI inference platforms are available from DigitalOcean, AWS SageMaker Inference, Akamai Inference Cloud, Baseten, Fireworks AI, Together AI, Modal, BentoML, vLLM, and NVIDIA Dynamo. What is an AI inference platform? An AI inference platform is a software and hardware stack designed to manage. Red Hat ® AI Inference Server provides fast and cost-effective inference at scale, across the hybrid cloud.
[PDF Version]